The 2022 report followed a rapid expansion in generative models. Diffusion systems made high-quality image generation broadly visible, while Chinchilla showed that model size alone was the wrong guide to training investment. New independent labs challenged the idea that leading results had to come from a few established organizations.
Diffusion models make image generation a major frontier
Diffusion models learn to undo noise and generate an image by progressively refining a noisy starting point. The report tracked DALL-E 2, Imagen, and Stable Diffusion, alongside early extensions into video and other types of data.
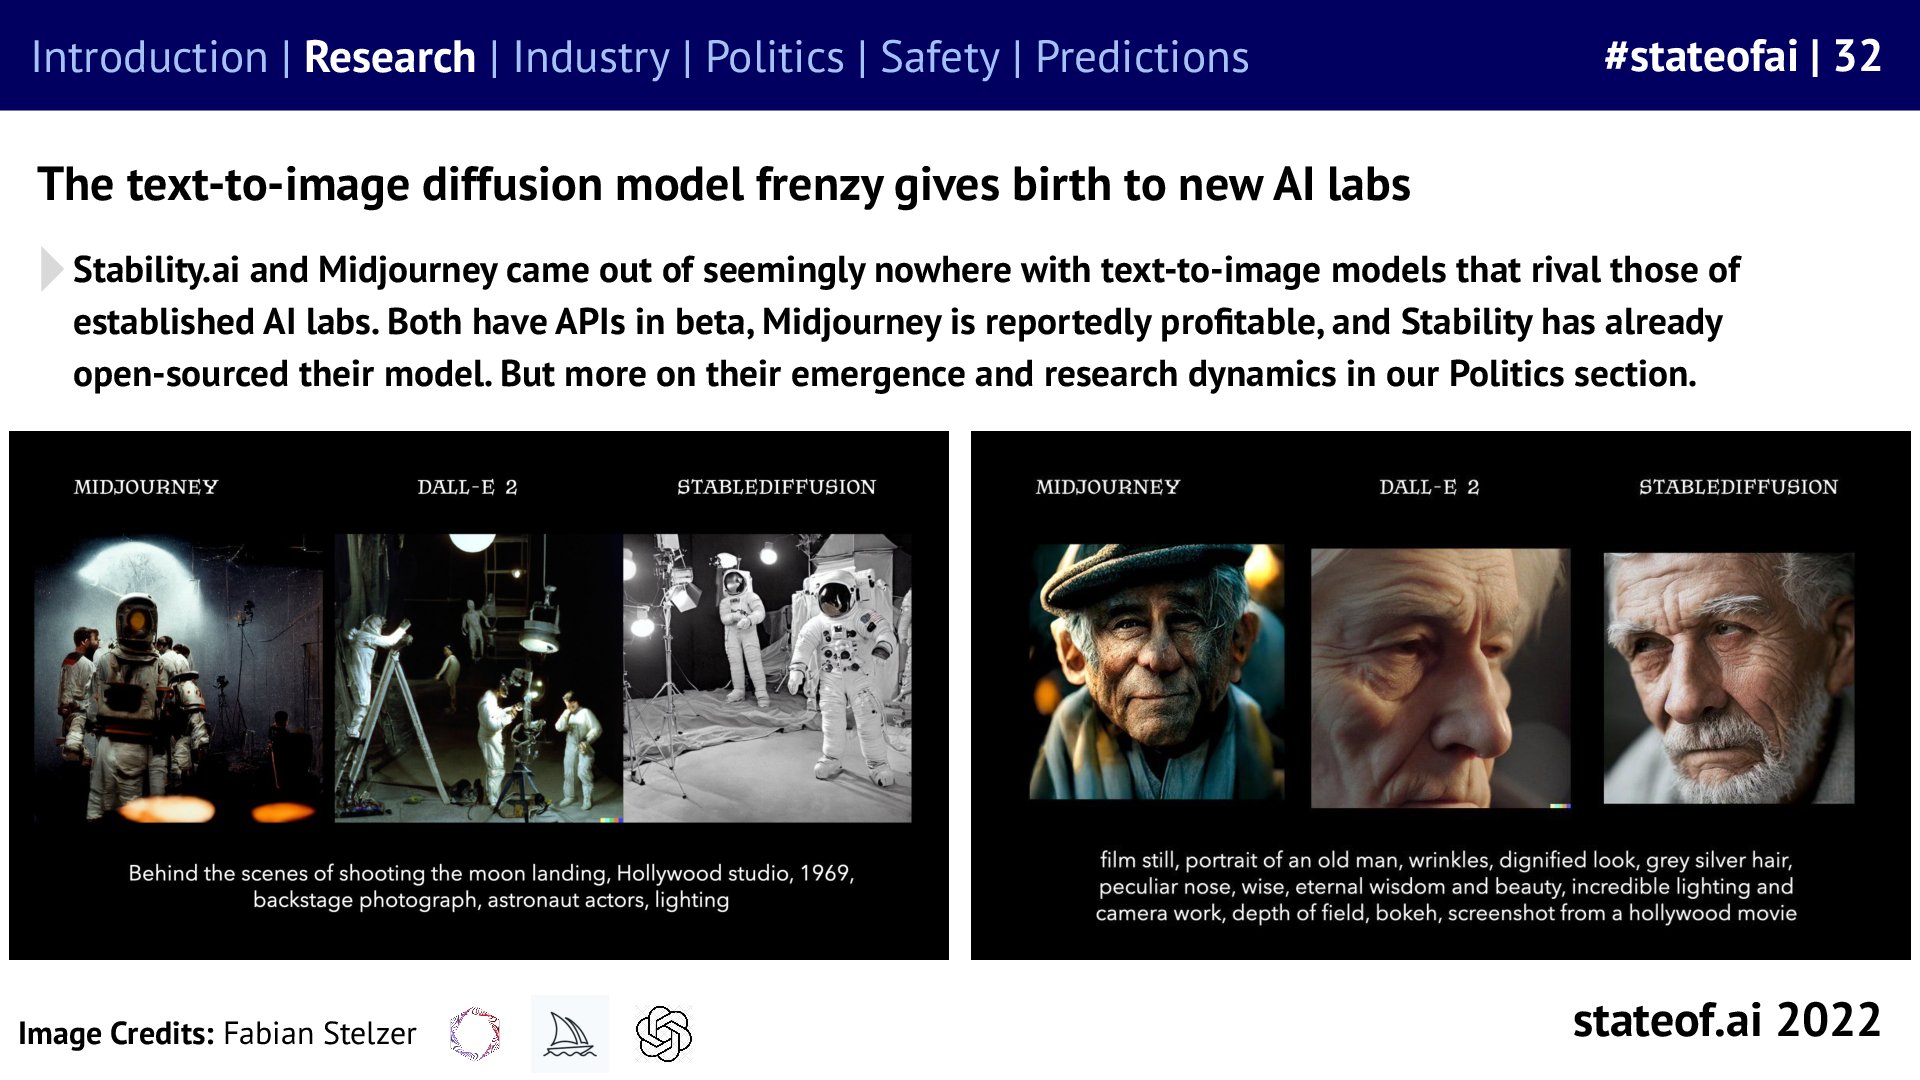
Stability AI and Midjourney appeared with competitive text-to-image systems. Stable Diffusion’s release let developers build on an available model, changing who could experiment and develop products. Availability and capability were separate from resolving licensing, misuse, or reliability questions.
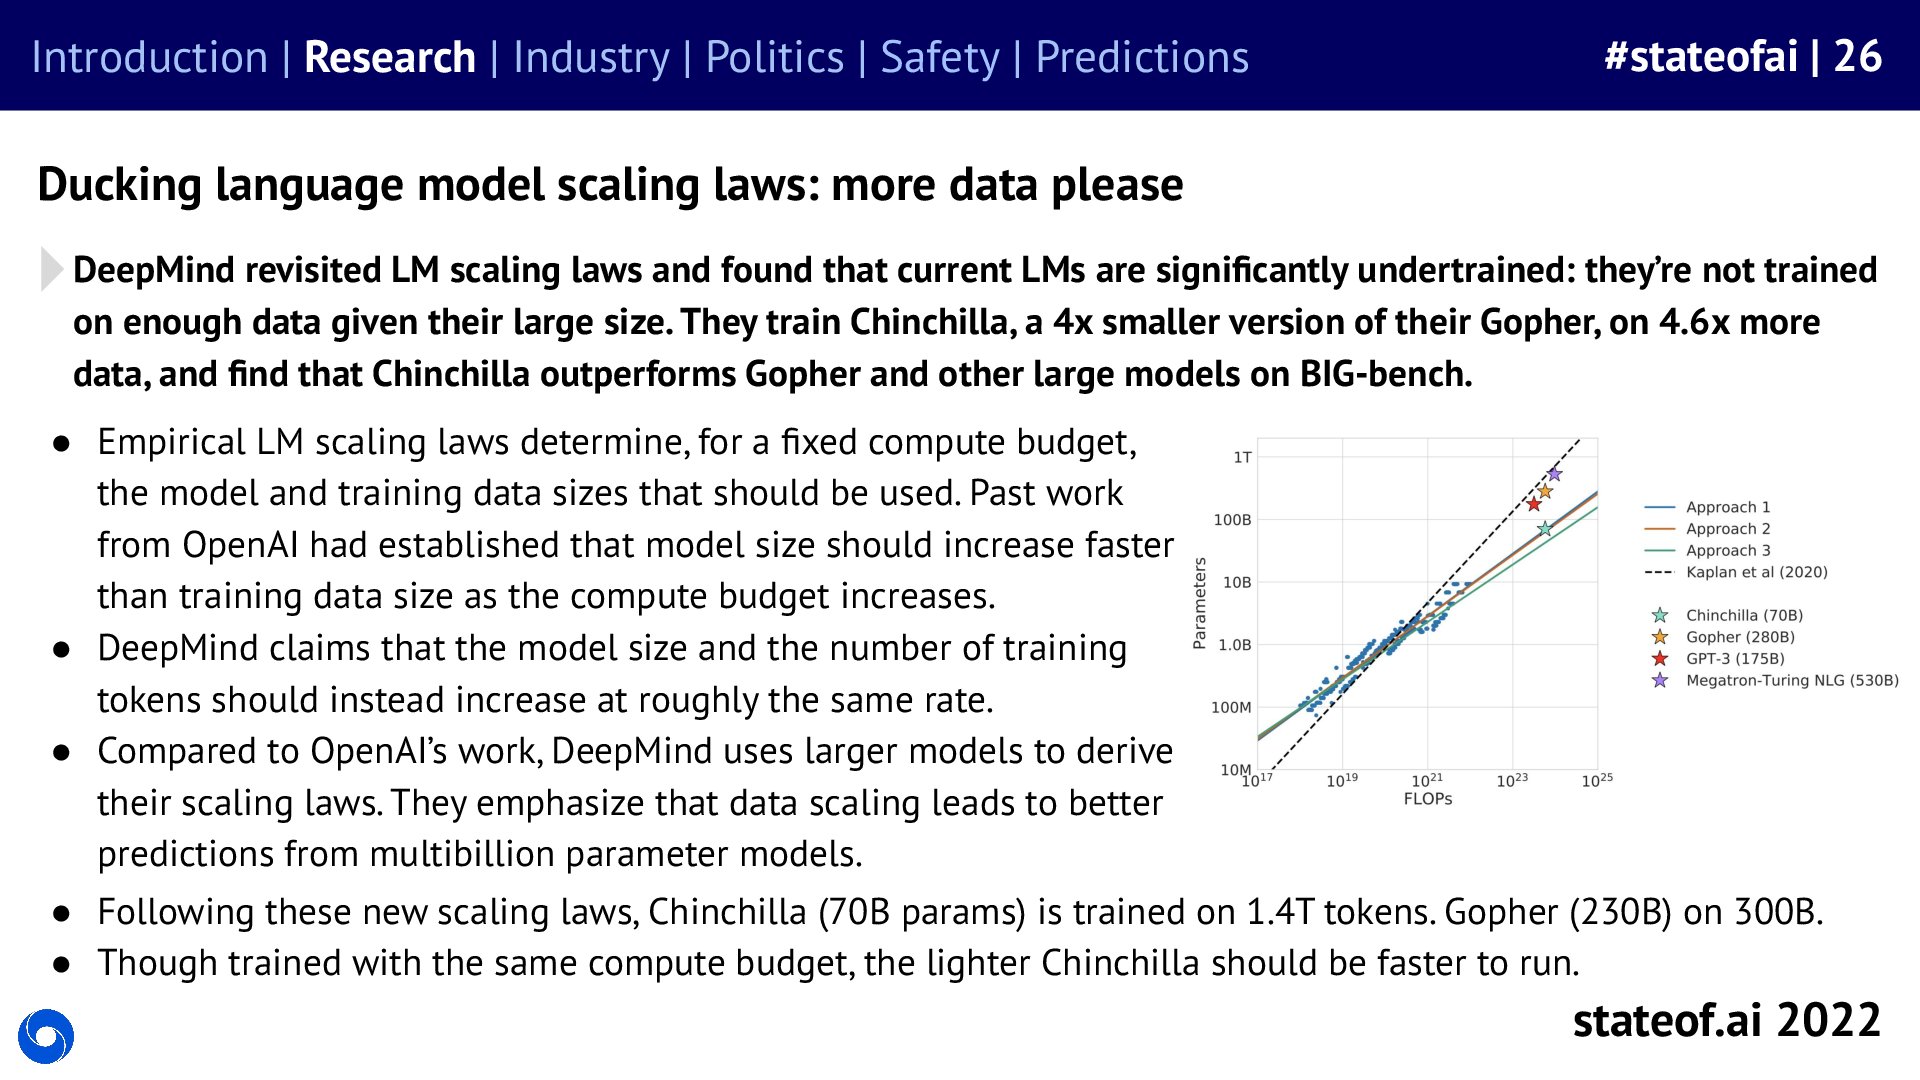
DeepMind’s 70-billion-parameter Chinchilla was trained on 1.4 trillion tokens. The report described improved results from allocating more of the compute budget to training data rather than simply increasing parameter count. The finding was about a compute-efficient training balance, not a claim that size no longer mattered.
Mathematical reasoning advanced through different approaches
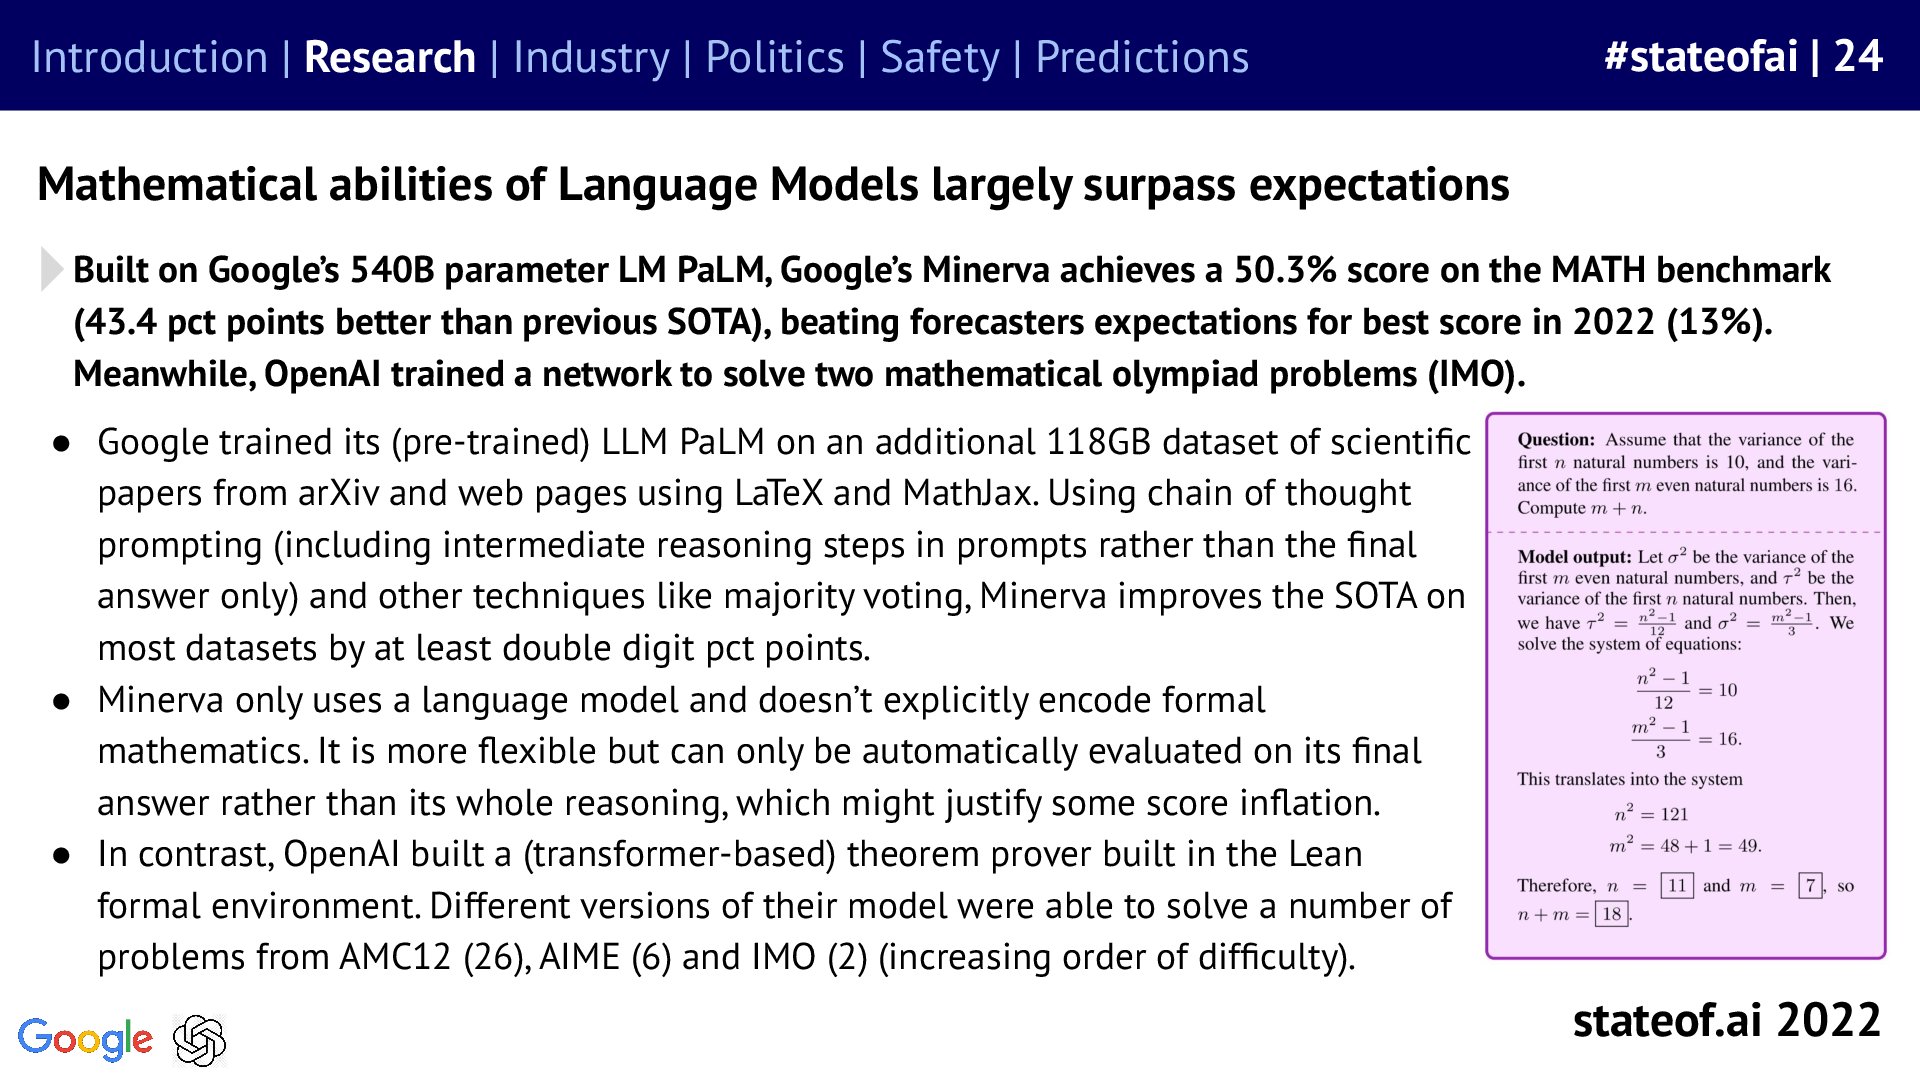
Google’s Minerva used a language model trained further on scientific and mathematical text, combined with intermediate reasoning steps and majority voting. It scored 50.3% on MATH in the report. OpenAI’s work instead used a theorem prover in the Lean formal environment. These were distinct approaches: Minerva’s benchmark could check a final answer without establishing that every reasoning step was valid, while formal proving imposed explicit rules on the proof.
Model specifications are not direct quality scores. The scaling finding applies to the studied training regime, while generative-image examples reflect the state of the field before ChatGPT’s public launch.
It showed the importance of training on more data for a given compute budget. The report described a 70B-parameter model trained on 1.4T tokens, rather than treating parameter count alone as the route to better performance.
The report described a 70-billion-parameter model trained on 1.4 trillion tokens. The pairing of those numbers mattered more to the argument than parameter count alone.
No. The report described a smaller model trained on substantially more data outperforming larger alternatives. It used the result to question how earlier training budgets had been allocated.
It meant that some large models had seen too little training data relative to their size and compute budget. The result pointed toward more balanced growth in data and parameters.
The report discussed DALL-E 2, Imagen, and Stable Diffusion. They illustrated the rise of diffusion approaches in text-to-image generation during the period covered.
No. It also discussed the method spreading toward other modalities, including video, audio, and molecular design. Those were research directions described in 2022.
Minerva generated mathematical reasoning with a language model and was evaluated automatically on final answers, achieving 50.3% on MATH in the report. The OpenAI work used the Lean formal environment to construct proofs. A correct final answer and a formally checked proof provided different kinds of evidence.
Historical snapshot published October 11, 2022. This web edition was prepared on 2026-10-11 from the online deck and original launch posts. Findings and forecasts retain their original time frame.
Benaich, Nathan, and Ian Hogarth. “Diffusion spreads and scaling laws change.” State of AI Report 2022. Historical report snapshot; web edition prepared 2026-10-11.