How to read this finding
The speedup and cost examples concern specific training configurations. They do not establish a universal ranking of hardware or reflect present-day cloud prices.
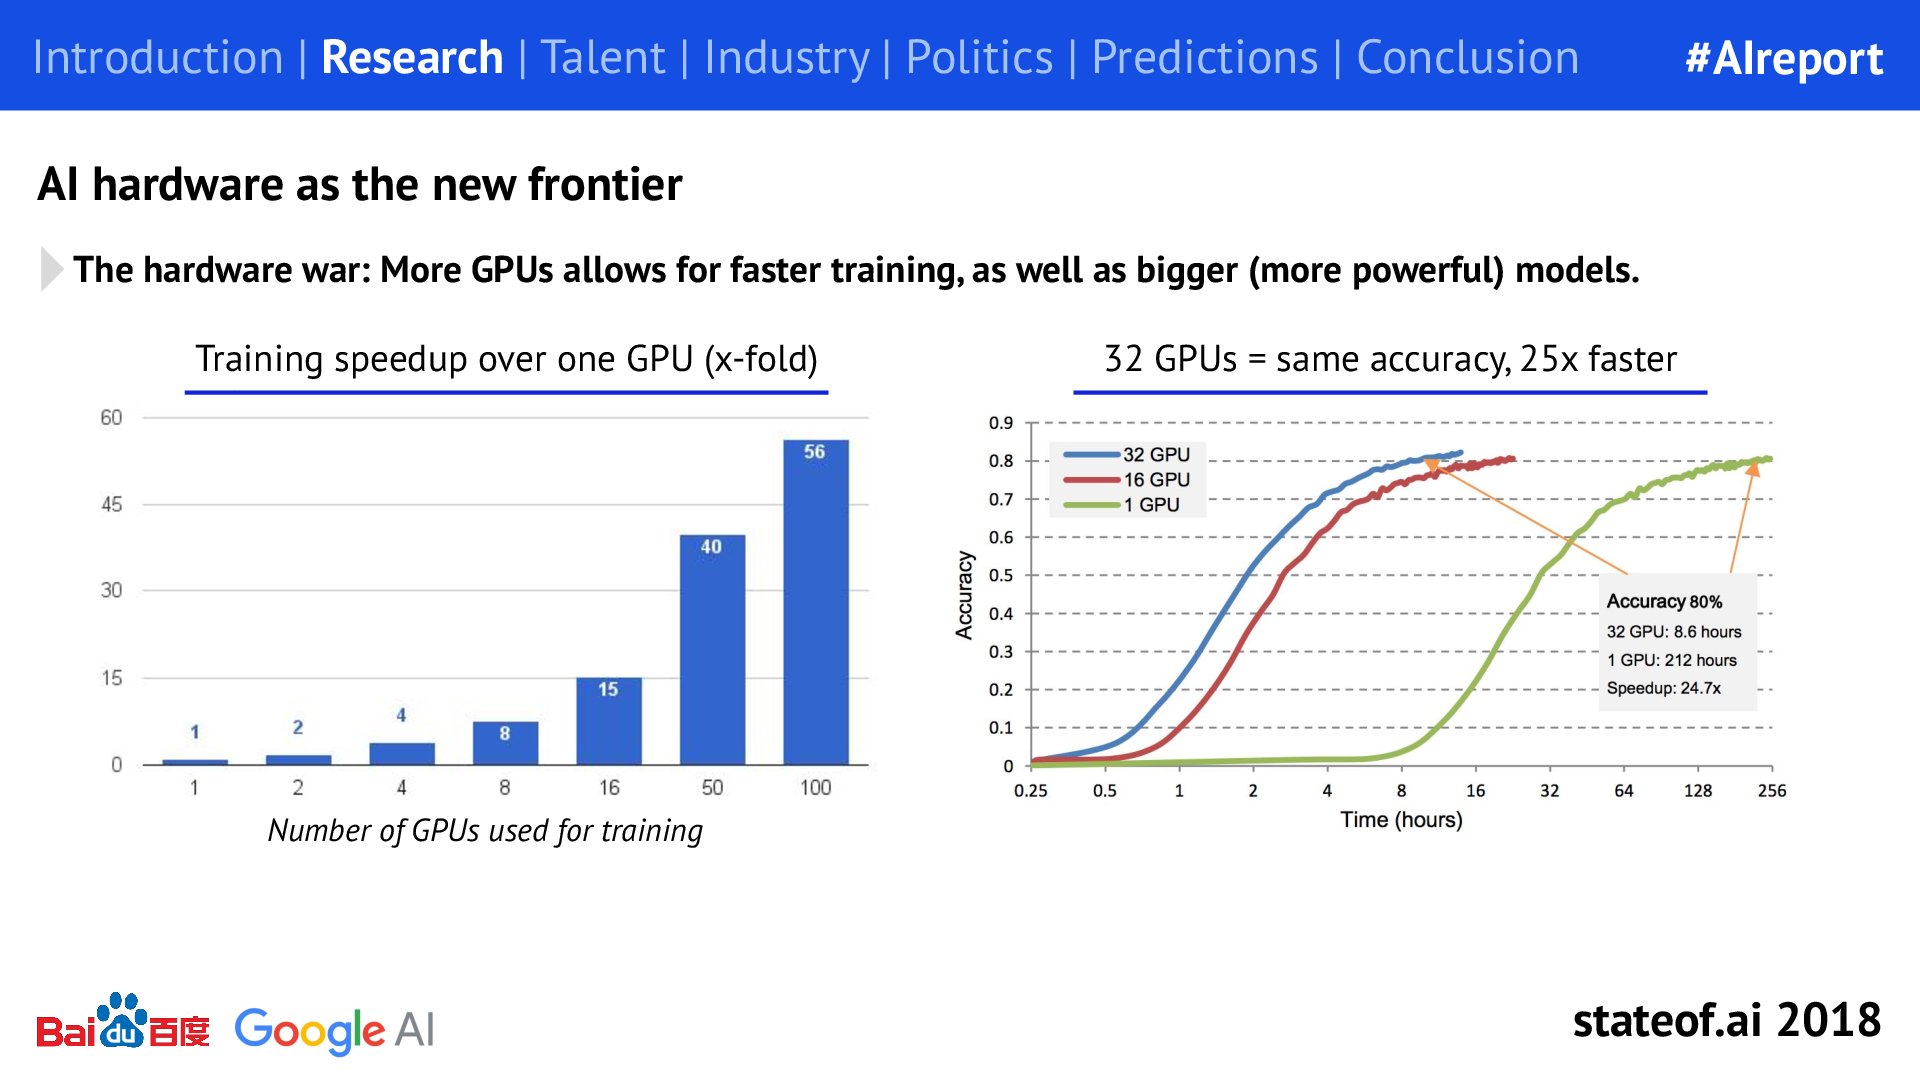
GPUs enabled faster training and larger models. In one comparison, 32 GPUs reached the same accuracy 25 times faster than one GPU, changing the pace at which experiments could be run.
The speedup and cost examples concern specific training configurations. They do not establish a universal ranking of hardware or reflect present-day cloud prices.
Evidence you can use
Historical snapshot: June 2018. Dates and populations are specified per row.
| Measure | Reported value | Definition and source |
|---|---|---|
| Parallel-training hardware | 32 GPUs | Hardware count in the reported comparison with one GPU.2018 report, PDF page 11 |
| Reported training speedup | 25x | Speedup at the same accuracy in that comparison.2018 report, PDF page 11 |
| Cost-comparison target | 75.7% top-1 accuracy | ImageNet target used in the cloud-cost comparison.2018 report, PDF page 21 |
The speedup and cost examples concern specific training configurations. They do not establish a universal ranking of hardware or reflect present-day cloud prices.
Historical snapshot published June 29, 2018. This web edition was prepared on 2026-10-11 from the online deck and original launch posts. Findings and forecasts retain their original time frame.
Benaich, Nathan, and Ian Hogarth. “Why did the 2018 report focus on GPUs?” State of AI Report 2018. Historical report snapshot; web edition prepared 2026-10-11.