How to read this finding
These results come from different systems and tasks. The planning result is an evaluation outcome; the code figures describe a specific industrial deployment. They should not be combined into a general agent success rate.
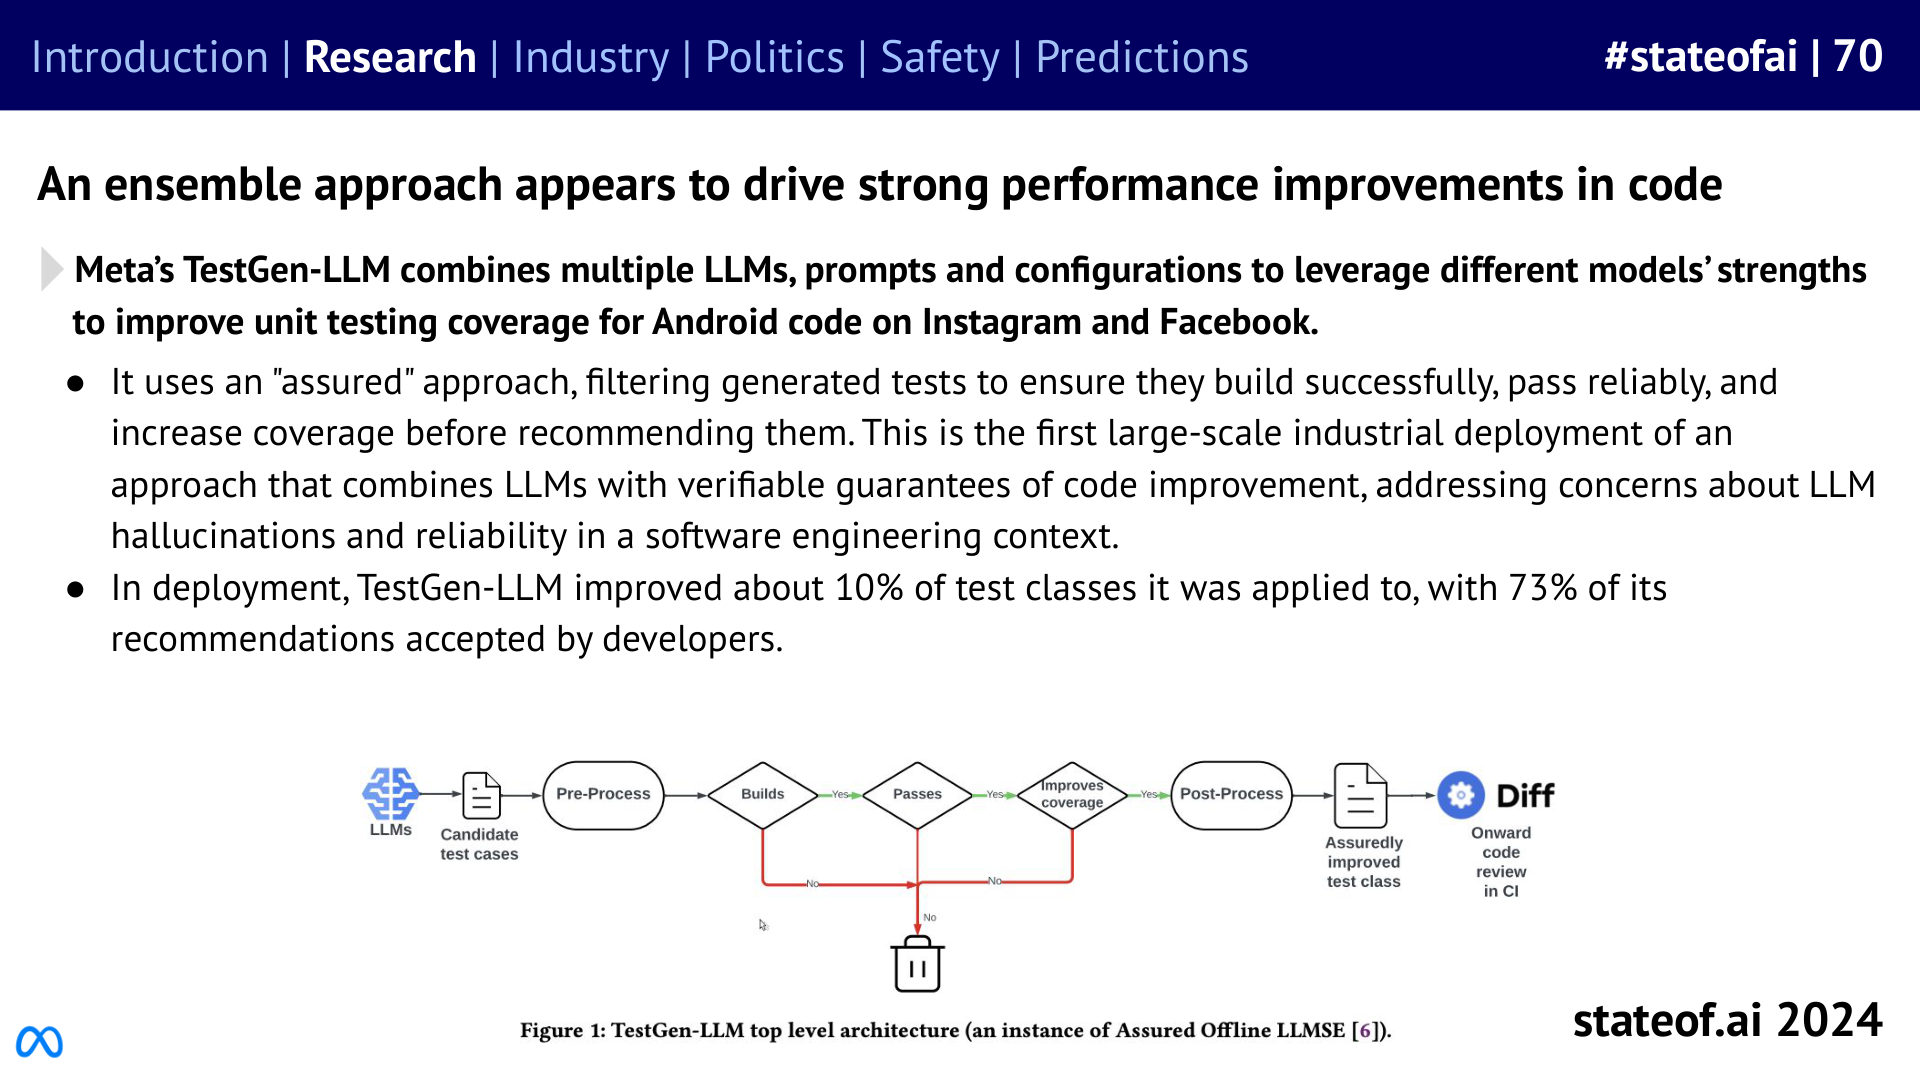
The report showed a concrete deployment in software testing: TestGen-LLM filtered generated tests for successful builds, reliable passes, and increased coverage before presenting them to developers.
These results come from different systems and tasks. The planning result is an evaluation outcome; the code figures describe a specific industrial deployment. They should not be combined into a general agent success rate.
Evidence you can use
Historical snapshot: October 2024. Dates and populations are specified per row.
| Measure | Reported value | Definition and source |
|---|---|---|
| Initial executable planning | 12% | GPT-4 result in the planning evaluation described by the report, before iterative external feedback.2024 report, slide 59 (PDF page 60) |
| Test classes improved | About 10% | Share of targeted test classes improved by TestGen-LLM in its deployment.2024 report, slide 70 (PDF page 71) |
| Test recommendations accepted | 73% | Developer acceptance of TestGen-LLM recommendations.2024 report, slide 70 (PDF page 71) |
These results come from different systems and tasks. The planning result is an evaluation outcome; the code figures describe a specific industrial deployment. They should not be combined into a general agent success rate.
Historical snapshot published October 10, 2024. This web edition was prepared on October 10, 2026 from the online deck and original launch posts. Findings and forecasts retain their original time frame.
Benaich, Nathan. “Where were AI agents useful in 2024?.” State of AI Report 2024. Historical report snapshot; web edition prepared 2026-10-10.