How to read this finding
Training size is not a quality score. TruthfulQA was designed to expose particular failure modes; its rates should not be treated as universal accuracy measures.
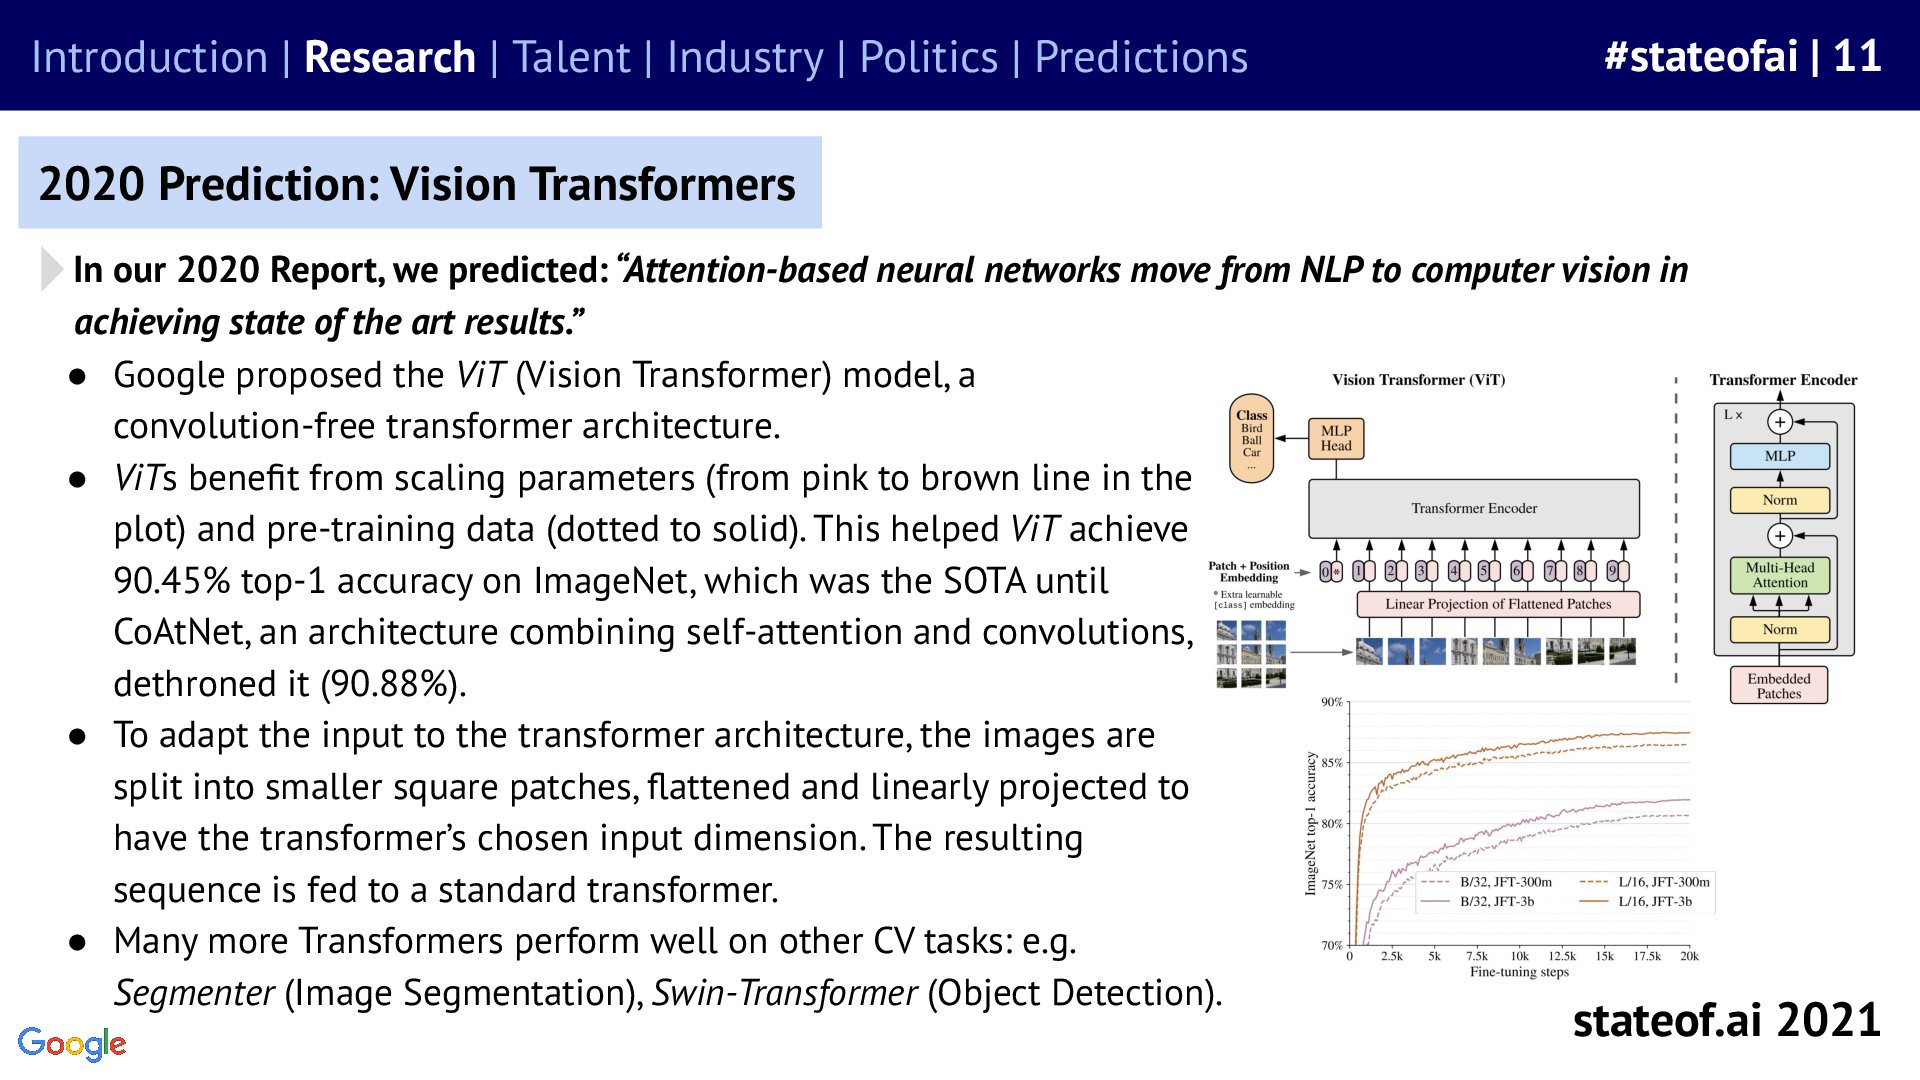
Vision transformers processed image patches as sequences, while models such as CLIP learned from paired text and images. This made the architecture useful across different types of data.
Training size is not a quality score. TruthfulQA was designed to expose particular failure modes; its rates should not be treated as universal accuracy measures.
Evidence you can use
Historical snapshot: October 2021. Dates and populations are specified per row.
| Measure | Reported value | Definition and source |
|---|---|---|
| CLIP training pairs | 400M | Text-image pairs used for pretraining.2021 report, slide 38 (PDF page 38) |
| Best model truthfulness | 58% | TruthfulQA comparison reported in the 2021 deck.2021 report, slide 44 (PDF page 44) |
| Human baseline truthfulness | 94% | Human comparison on the same benchmark.2021 report, slide 44 (PDF page 44) |
Training size is not a quality score. TruthfulQA was designed to expose particular failure modes; its rates should not be treated as universal accuracy measures.
Historical snapshot published October 12, 2021. This web edition was prepared on 2026-10-11 from the online deck and original launch posts. Findings and forecasts retain their original time frame.
Benaich, Nathan, and Ian Hogarth. “Why were transformers important beyond language in 2021?” State of AI Report 2021. Historical report snapshot; web edition prepared 2026-10-11.