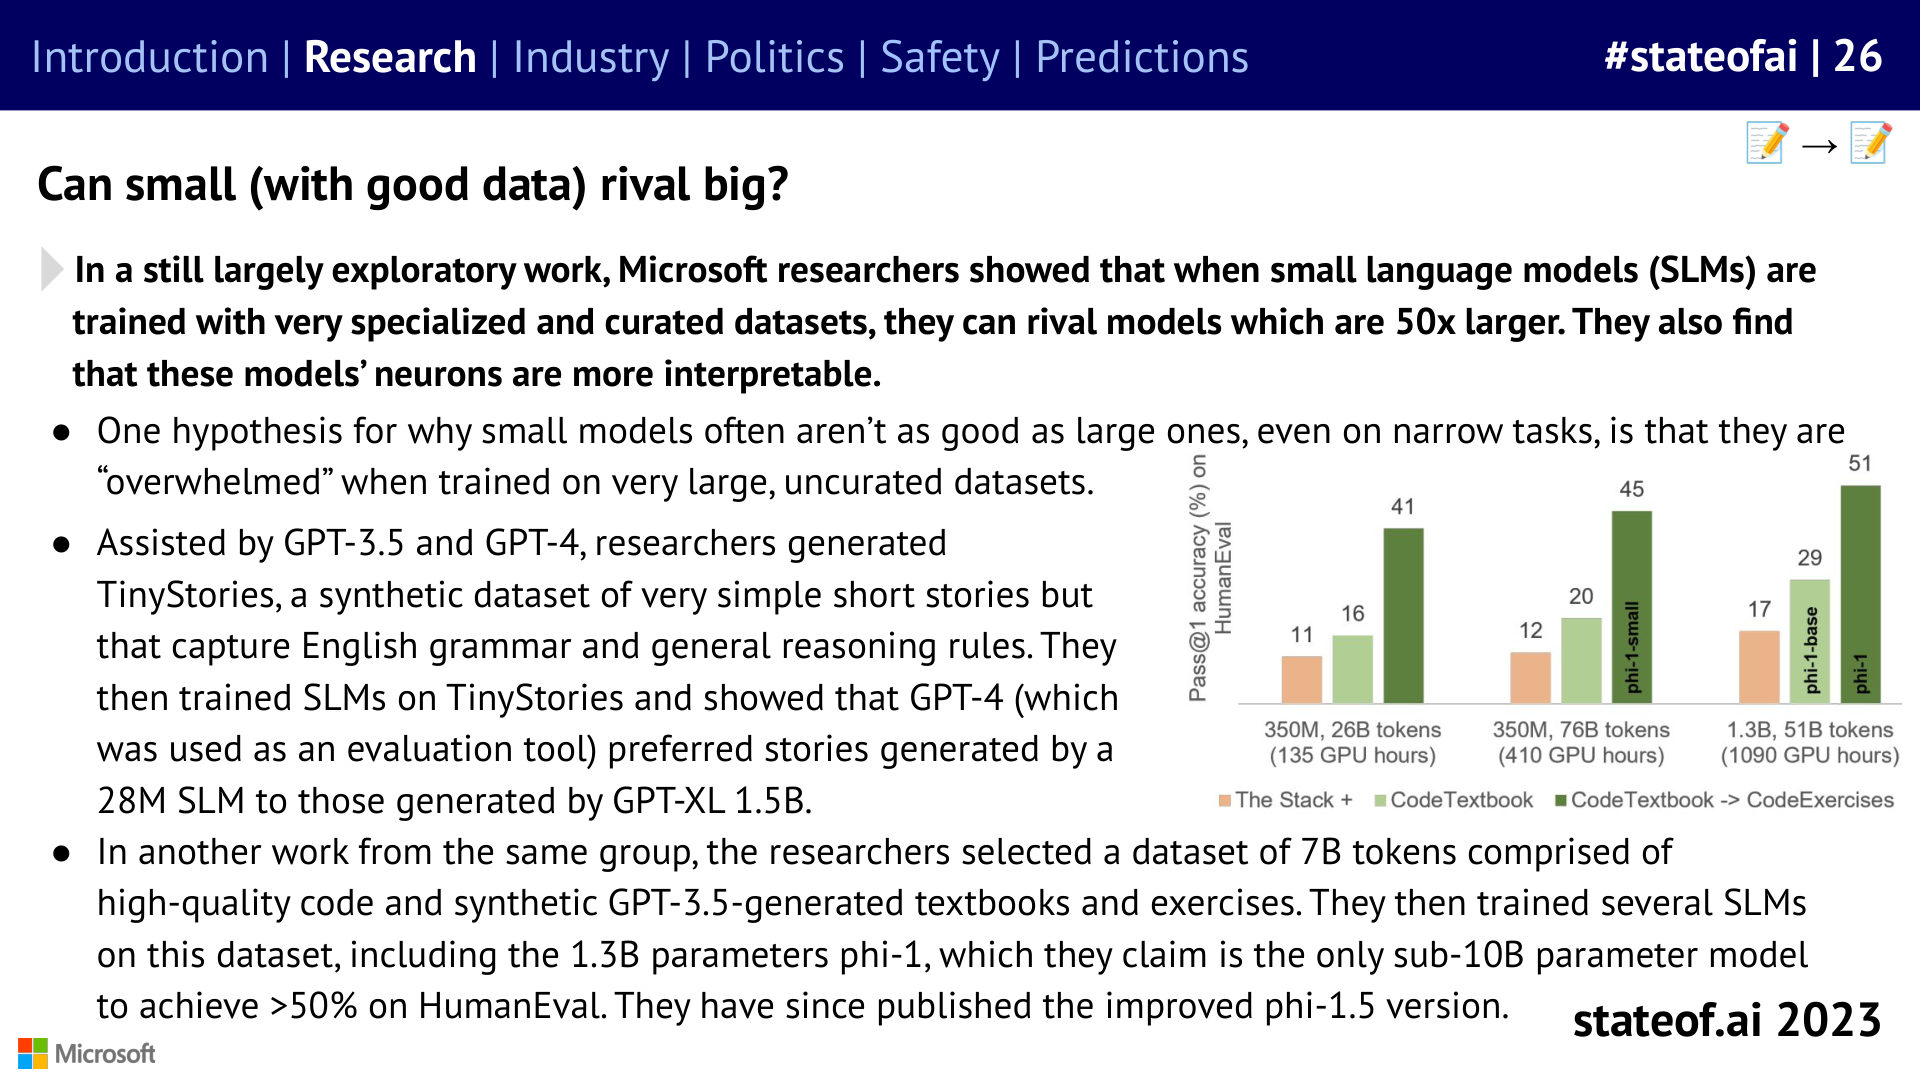
GPT-4 sets the benchmark
The report described GPT-4 as a substantial improvement over its predecessors, including stronger performance on reasoning and knowledge tasks. Reinforcement learning from human feedback improved some behaviors, but hallucinations remained. Better answers did not remove the need to examine how a model was evaluated or where it still failed.
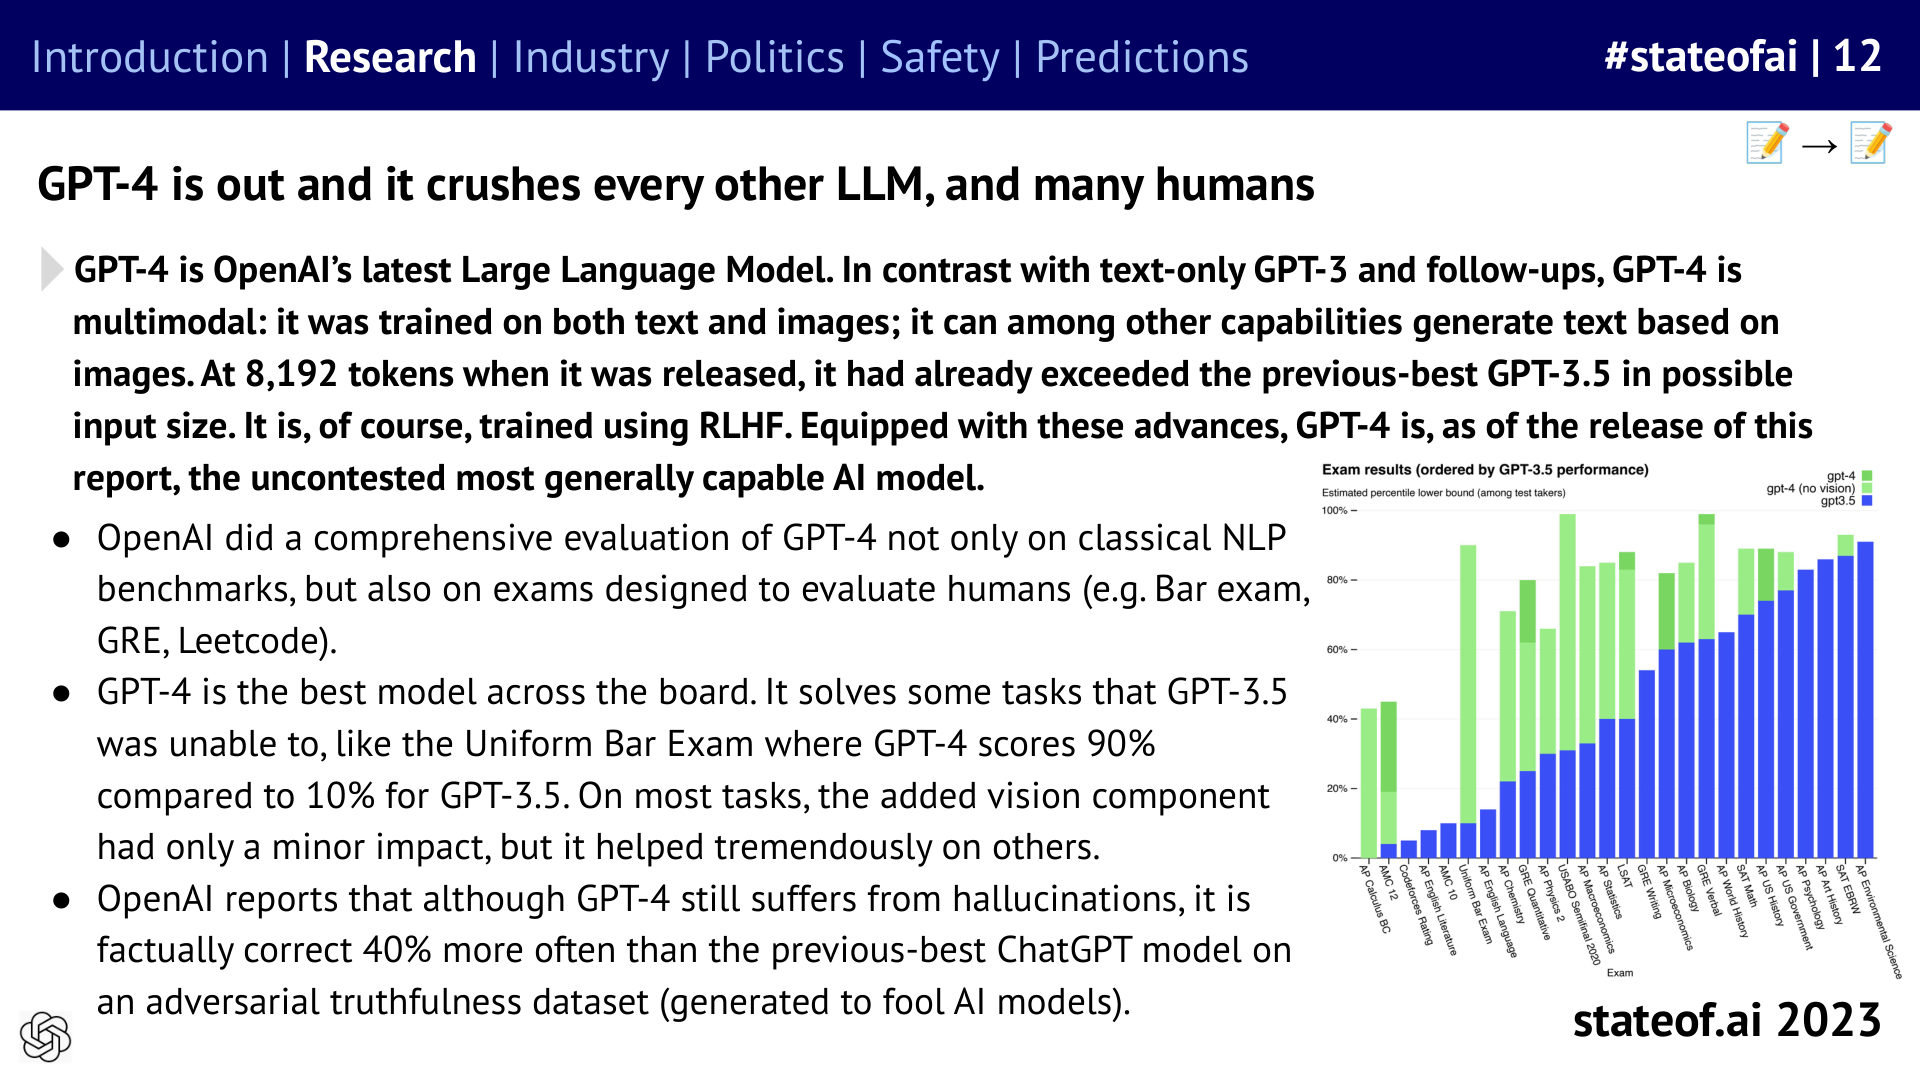
Llama 2 gives builders another route
Meta’s Llama 2 used a two-trillion-token pretraining corpus and additional instruction tuning and human feedback. The 70B model was competitive with ChatGPT on many tasks but lagged in coding, where a specialized Code Llama variant performed better. The release permitted broad commercial use subject to license conditions, rather than unrestricted use by every company.
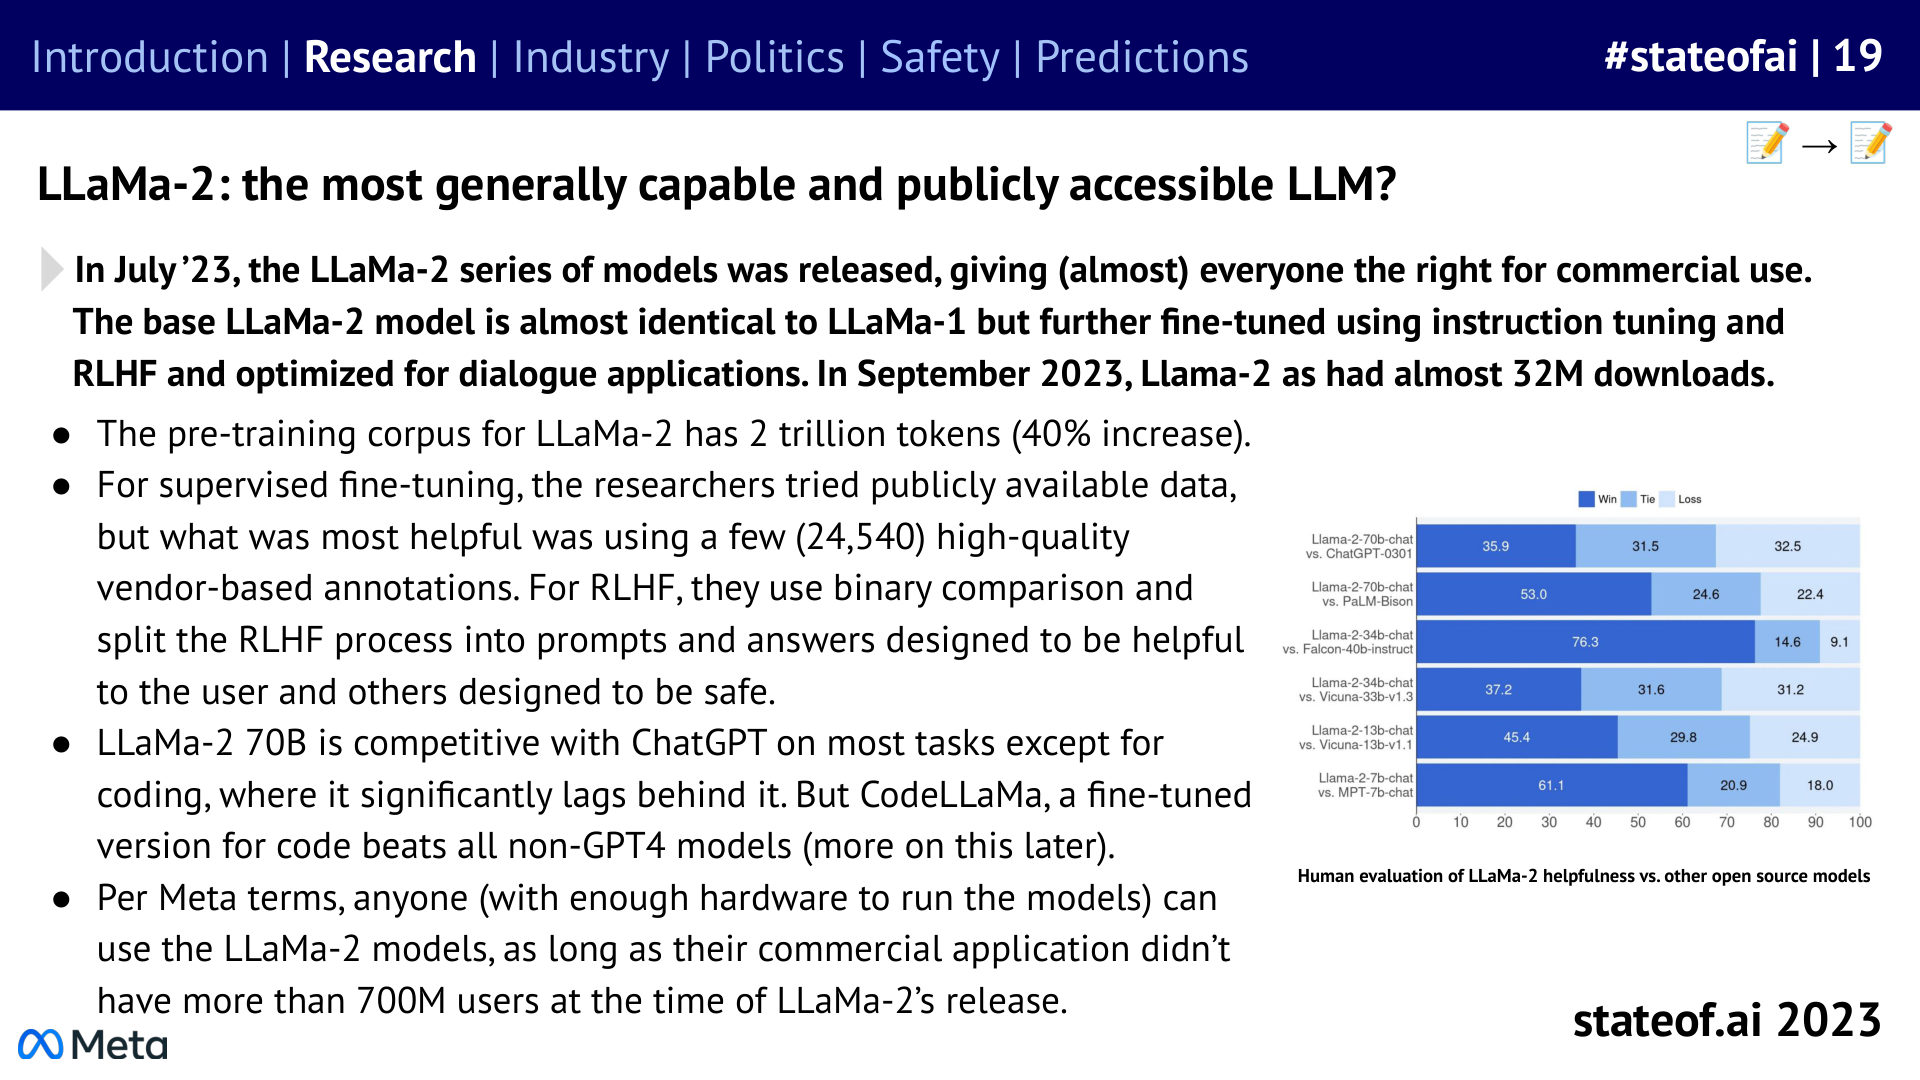
Small models benefit from carefully selected data
Microsoft’s TinyStories and phi work explored whether narrow, curated datasets could produce useful capabilities in much smaller models. A 28-million-parameter story model compared favorably with a much larger model under a GPT-4-based evaluation. These were task-specific results; they did not establish that a small model could replace a frontier model across all uses.